sparklens
Client-side Spark event-log visualizer. Drop in a log and get a stage DAG plus skew, spill and shuffle findings — everything runs in the browser, your log never leaves it.
AI Data Engineer
I build data platforms that move 50M+ records a day — reliably, observably, and on time.
About
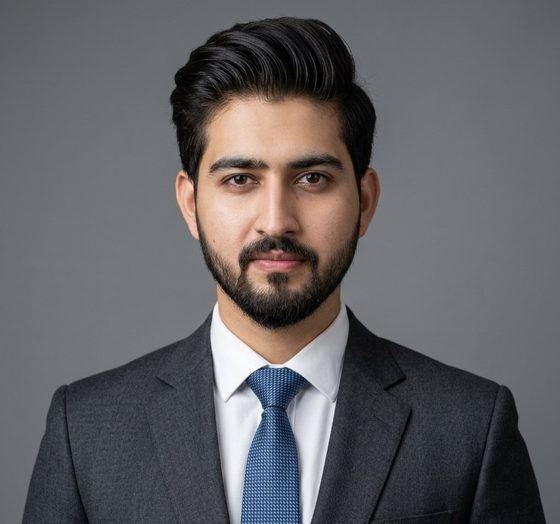
I'm an AI Data Engineer with 4 years building production data platforms on AWS and Azure Databricks for a Fortune 500 pharmaceutical client — from CDC-based migrations of 15+ TB to medallion lakehouses serving 40+ dashboards.
My happy place is the unglamorous middle: schema evolution that doesn't page anyone at 3 AM, backfills that just work, and streaming pipelines with honest latency numbers.
Experience
Tata Consultancy Services · Client: Fortune 500 pharmaceutical (Life Sciences) · Noida, India
Projects
Client-side Spark event-log visualizer. Drop in a log and get a stage DAG plus skew, spill and shuffle findings — everything runs in the browser, your log never leaves it.
Ephemeral bring-your-own-data RAG. Upload a CSV, chat with it through retrieval — then it self-deletes after 7 days. No accounts, no data kept.
Natural-language to SQL studio. Hybrid dense + BM25 retrieval with reciprocal-rank fusion, schema pruning, and a repair loop that fixes its own bad queries.
Pharmaceutical Q&A over DailyMed drug labels. Hybrid retrieval, conversational follow-ups, and a ReAct agent mode — every answer fully cited.
Personal WireGuard VPN. Kotlin Android client paired with one-command server provisioning scripts.
Self-hosted chat platform — communities, channels, DMs, voice and screen sharing. NestJS + React over Postgres and Redis, LiveKit for real-time media, all running on a free-tier Oracle VM.
Skills
Verify the AWS cert at the link above with validation no. 7314d9d0ce9349b5b35313dc1d25dbb6
Contact
Currently open to data engineering roles and interesting collaborations.